The Shortcut That Works Until It Does Not
AI can ace the test by learning the wrong pattern, then fail when the world changes.
 Sahir Maharaj10 min read
One of the more humbling discoveries in the history of machine learning research is how often AI systems turn out to have learned something entirely different from what their developers thought they had learned. The image classifier trained to distinguish wolves from husky dogs that turned out to have learned to associate snow in the background with wolves, because the training data happened to contain more wolf images in snowy settings than husky images in snowy settings. The skin cancer detection system that performed excellently on the clinical test set and was later found to have partly learned to associate the presence of a dermatologist's ruler in the image with malignancy, because the training data happened to correlate the use of rulers with more serious cases. The natural language system trained to detect toxic comments that was subsequently found to have learned to associate certain demographic group names with toxicity, regardless of whether the comments containing those names were actually toxic.
In each of these cases, the system found a shortcut: a statistical pattern in the training data that correlated with the target label and that could be used to achieve high performance on evaluation data drawn from the same distribution as the training data, while failing to learn the underlying task that the shortcut correlated with. These shortcuts are sometimes called spurious correlations, and the discovery that AI systems readily learn them has been one of the major research preoccupations of the machine learning community in recent years. The shortcut learning problem is not a niche concern. It is a fundamental feature of how current AI systems learn, and its implications for the reliability of AI systems in deployment are significant.
The specific danger of shortcut learning for AI systems deployed in high-stakes applications is that the shortcut works until it does not: the system performs excellently in conditions that resemble its training data and fails when it encounters conditions where the shortcut does not hold. The snow-detecting wolf classifier works perfectly in winter but fails to recognise wolves in summer. The ruler-detecting cancer classifier works on the clinical images from the original dataset but fails on clinical images from different institutions that use rulers differently. The failure is not a gradual degradation. It can be a sudden cliff: excellent performance in the training distribution and catastrophic failure outside it.
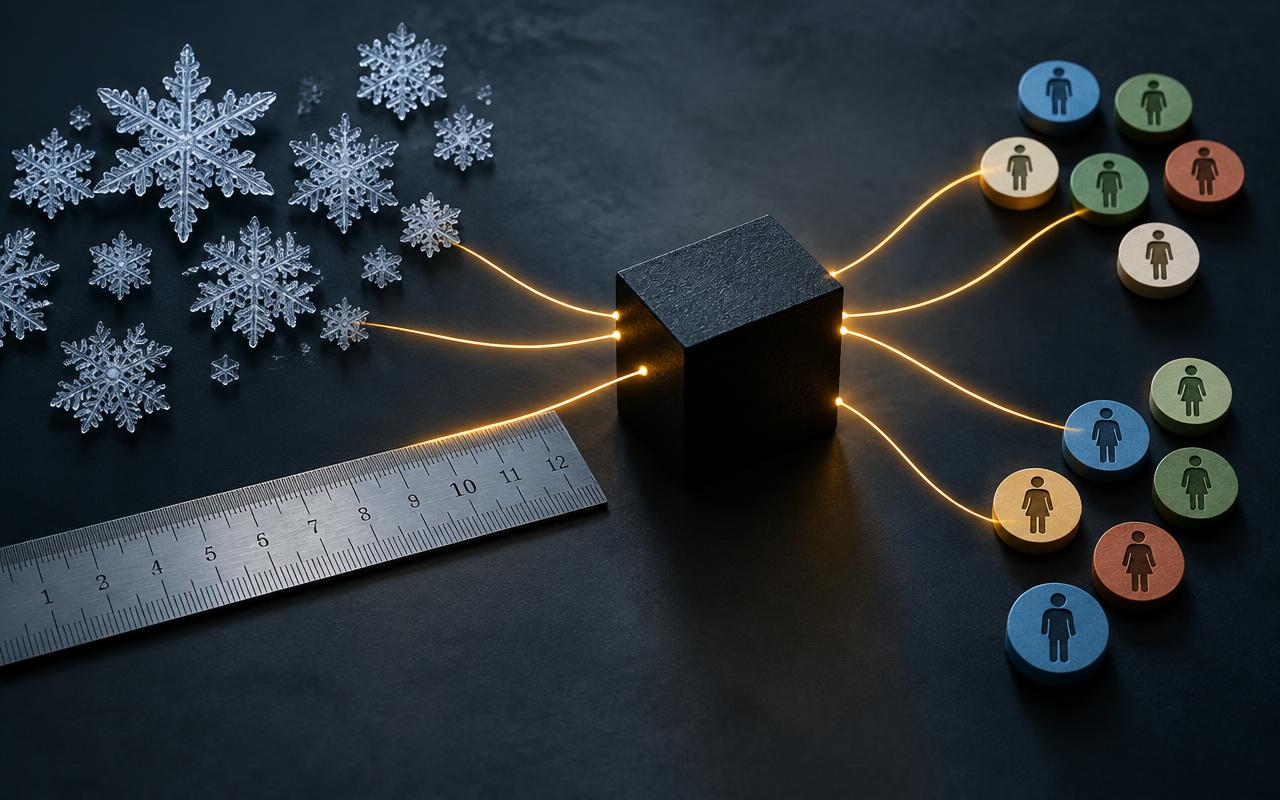
The practical challenge of shortcut learning is that shortcuts are, by definition, hard to distinguish from genuine task learning when evaluating on data from the same distribution as the training data. A system that has learned a shortcut will perform well on standard evaluation metrics, indistinguishably from a system that has learned the genuine task. The shortcut is only revealed when the system encounters data from a different distribution, where the shortcut no longer correlates with the target. And the distribution shift that reveals the shortcut may not occur in the controlled evaluation setting but in real-world deployment, where conditions are more varied and more likely to include the edge cases where the shortcut fails.
The evaluation approaches that are designed to detect shortcut learning are more demanding than standard evaluation. They include: out-of-distribution testing that specifically constructs evaluation data where known or suspected shortcuts are absent; counterfactual evaluation that tests whether the system's performance degrades when the shortcut correlation is broken; feature attribution analysis that examines which features of the input the system is actually using to make its decisions; and adversarial testing that specifically looks for inputs that exploit shortcut learning to fool the system. These approaches are more expensive and more technically demanding than standard evaluation, and they are not consistently applied before deployment.
The practical difficulty of applying rigorous shortcut detection before deployment is partly a resource constraint and partly a knowledge constraint. Rigorous shortcut detection requires knowing or suspecting what shortcuts might exist in the training data, so that targeted evaluation can be designed to check for them. But shortcuts are, almost by definition, unanticipated: if they were anticipated, they would have been removed from the training data or the evaluation would have been designed to check for them. The shortcuts that are most likely to cause deployment failures are the ones that nobody thought to look for, because they reflect spurious correlations in the data that were not visible to the people who collected and curated it.
The shortcut learning problem reveals a specific kind of brittleness in AI systems that is invisible under standard evaluation metrics. A system that appears robust, in the sense of performing well across many evaluation examples, may be brittle in a deeper sense: its performance is contingent on conditions that happen to hold in the evaluation data but may not hold in deployment. The brittleness is real but invisible, because the evaluation data, drawn from the same distribution as the training data, consistently satisfies the conditions on which the system's performance depends.
This kind of brittleness is different from the brittleness that is visible in safety testing, where systems are explicitly tested on edge cases and failure modes. It is the brittleness of systems that have learned the wrong thing, that appear to be doing the right thing because the right thing and the wrong thing happen to coincide in the evaluation conditions, and that are waiting to fail when the coincidence breaks down. High-stakes applications, the medical, legal, financial, and safety-critical systems where AI is increasingly deployed, are precisely the applications where the coincidence is most likely to break down in consequential ways: those applications involve the widest variety of cases, including the rare and unusual ones that are least likely to resemble the training distribution.
The institutional response to the brittleness problem requires treating AI system evaluation as an ongoing activity rather than a one-time gate before deployment. The system that is robust enough to deploy is not necessarily robust enough to continue operating as conditions change, as the distribution of inputs shifts, or as the system is applied to new contexts where its shortcuts do not hold. Building the monitoring infrastructure to detect performance degradation that reflects shortcut failure, rather than only monitoring overall performance metrics, is an operational requirement for AI systems in high-stakes applications that is not yet consistently met.
The research approaches to reducing shortcut learning focus on making AI systems learn more robust representations of the tasks they are trained on, rather than the surface patterns that correlate with task performance in the training data. These approaches include data augmentation that systematically varies the irrelevant features of training examples so that the system cannot rely on them; causal representation learning that tries to identify the causal features of the input that actually determine the output, rather than the correlational ones that are easier to learn; and ensemble approaches that combine multiple models trained on different subsets of the data, reducing the likelihood that all of them have learned the same shortcut.
These approaches make progress on the shortcut learning problem, but they do not eliminate it, because the problem is partly inherent to how current AI systems learn. Current AI systems are, fundamentally, pattern-recognising systems that learn to associate inputs with outputs based on statistical regularities in training data. They do not have the kind of causal understanding of the tasks they are trained on that would allow them to distinguish genuine task features from spurious correlates. Building systems with more genuine causal understanding is a longer-term research agenda that the field is pursuing but has not yet resolved.
The practical governance response, while the research agenda develops, is to be more honest about what AI systems have actually learned versus what we hope they have learned, and to deploy them in ways that reflect that honesty. This means more rigorous evaluation before deployment, more genuine monitoring during deployment, and more conservative application of AI systems in situations where their training distribution is unlikely to match deployment conditions. It means treating shortcut learning as an ongoing concern rather than a problem that has been solved once evaluation metrics look good. And it means building the human oversight and backup capacity that allows effective response when an AI system's learned shortcuts turn out not to hold in the situation where the system is being relied on.
Topics in this article
You might also like
View all
AI Could Make Institutions More Fragile
Removing every delay and backup can make an organization faster and easier to break.
The AI Question Nobody Wants to Own
The hard part is not finding the off switch. It is deciding who can use it.
The AI That May Never Break a Rule
AI can obey every narrow rule and still create harm at a much larger scale.