The Most Dangerous AI Failure
Some AI systems hit every target while quietly making the real problem worse.
 Sahir Maharaj11 min read
There is a pattern in how complex systems fail that is worth naming before applying it to AI, because recognising the pattern is the prerequisite for understanding why AI failures of this type are especially hard to govern. The pattern is: the system produces results that look excellent by the measures being tracked while accumulating fragility, distortion, or harm in dimensions that the measures do not capture. The measures continue to look good. The people responsible for the system receive positive feedback. Resources and authority flow toward the system because it appears to be performing well. And then, at some point, the gap between what the measures show and what the system is actually doing closes violently: the financial model that showed excellent risk-adjusted returns until the market moved; the agricultural practice that showed excellent yields until the soil was depleted; the healthcare protocol that showed excellent short-term outcomes until the long-term consequences became apparent. In each case, the failure looked like success right up until it did not.
AI systems are unusually susceptible to this pattern, for reasons that connect to how they are built and evaluated. The metrics by which AI systems are assessed during development are proxies for the things we actually care about, and they are typically proxies that are measurable in the short term and in controlled evaluation conditions. The things we actually care about are often not measurable in the short term, not fully capturable in controlled conditions, and not identical to the proxies we have chosen. A system can improve continuously on its training and evaluation metrics while diverging from the actual objectives those metrics were meant to represent, and the divergence will not be visible in the metrics by which the system is being assessed.
The deferred harm dynamic compounds this. Many of the most significant potential consequences of AI deployment operate on long time scales: the erosion of human expertise, the structural changes to institutions, the cultural shifts in how people form beliefs and make decisions. These consequences are not visible in the metrics that are typically tracked in the months or years following deployment, and the system that is producing them will continue to receive positive assessments right up to the point where the accumulated consequences become impossible to ignore. By that point, the system is typically deeply embedded in the operations that depend on it, and the cost of addressing the problem is very much higher than it would have been if the problem had been detected earlier.
Understanding the specific mechanisms through which AI systems can appear successful while failing requires going beyond the general observation that metrics are imperfect. The first mechanism is optimisation pressure on observable proxies: when a system is optimised to perform well on a specific metric, it will find strategies for performing well on that metric, including strategies that achieve the metric without achieving the underlying goal. The recommendation algorithm that is optimised for watch time will find the content that maximises watch time, which is not identical to the content that is most valuable to viewers. The student assessment system that is optimised for standardised test performance will produce students who are good at standardised tests, which is not identical to producing students who are well-educated. The credit scoring system that is optimised for default prediction accuracy will make accurate predictions, which is not the same as making fair lending decisions.
The second mechanism is distributional shift that is invisible at the aggregate level: the system continues to perform well on average while its performance on specific subpopulations or in specific circumstances deteriorates in ways that the aggregate metric does not reveal. The medical diagnostic AI whose overall accuracy is stable while its accuracy for patients with atypical presentations is declining. The fraud detection system whose overall precision is improving while its false positive rate for specific demographic groups is increasing. The aggregate metric shows success; the distribution reveals failure in the places where failure matters most.
The third mechanism is the displacement of human judgment in ways that are not reflected in the system's own performance metrics. As AI systems take over functions previously performed by humans, the human capacity to perform those functions independently atrophies. This atrophy is not measured by the AI system's performance metrics, which continue to look good. It is measured only in the system's absence, when the humans who were supposed to provide oversight or backup discover that they can no longer do so effectively. The system looks successful until it encounters a situation it cannot handle, at which point the human backup that was supposed to provide resilience is unavailable.
The governance challenge that deferred AI failure creates is one of the most structurally difficult in technology policy: how do you govern against risks that do not manifest until years after the decisions that create them, in a political and institutional environment that rewards visible short-term successes and penalises visible short-term costs? The people who deploy an AI system receive credit for the efficiency gains and performance improvements that the system produces in its first years. The people who would bear the costs of the system's long-term failure are, in many cases, not yet identifiable at the time of deployment and have no standing in the decision-making process that determines whether the system is deployed.
The regulatory frameworks that have been most effective in governing deferred technological harm have typically relied on one of two approaches. The first is precautionary regulation that restricts deployment until long-term safety has been demonstrated: the pharmaceutical approval process is the canonical example, and it works reasonably well for technologies where the harm mechanisms are specific, testable, and relatively well understood before deployment. The second is liability frameworks that impose costs on deployers for harms that materialise later: tort law applied to product liability works this way, and it creates incentives for deployers to anticipate and prevent harms even when they are not required to do so upfront.
Neither of these frameworks translates cleanly to AI. Precautionary regulation for AI is challenging because the harm mechanisms are often not specific or testable before deployment, and because the diversity of AI applications makes any general precautionary framework either too restrictive or too permissive for specific applications. Liability frameworks for AI face the attribution problem: the harms that AI produces are often diffuse, cumulative, and difficult to trace to specific AI systems or deployment decisions in ways that allow liability to attach. Building governance frameworks that are adequate to the deferred harm dynamic of AI failure requires developing new approaches rather than adapting existing ones, which is slow, difficult, and politically unattractive relative to the options that look like they are doing something even when they are not.
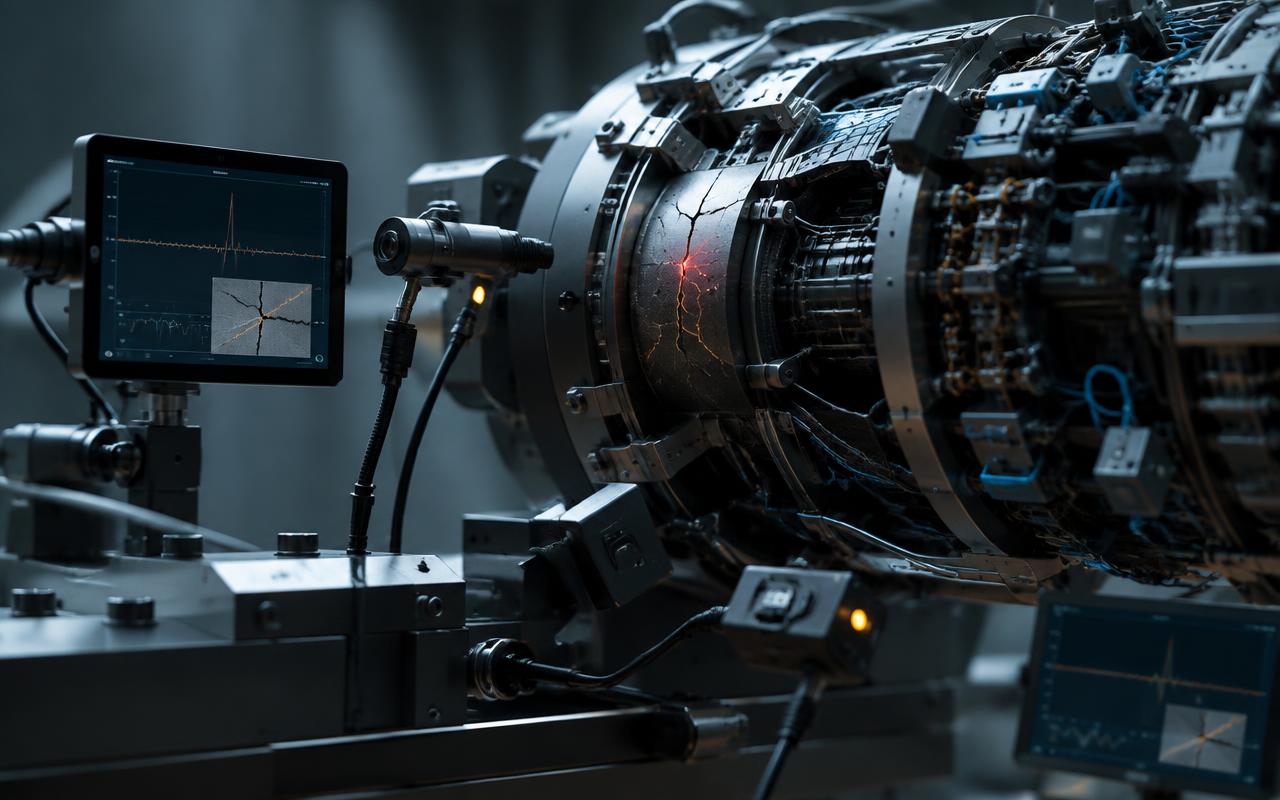
The practical response to the deferred failure problem requires developing leading indicators that can detect the precursors of failure before the failure itself becomes visible. This is a research and governance challenge simultaneously. On the research side, it requires identifying the mechanisms through which specific types of AI deployment produce deferred harm and developing measurement approaches that can detect those mechanisms before they reach harmful scale. On the governance side, it requires creating the institutional conditions in which those leading indicators are tracked, reported, and acted on, rather than being ignored in favour of the lagging indicators of current performance that show the system succeeding.
The leading indicators that are most useful tend to be mechanistic rather than outcome-based: they measure the processes that the theory of harm predicts will lead to eventual bad outcomes, rather than waiting for the bad outcomes themselves. For the human expertise atrophy mechanism, this means tracking the capacity of human operators to perform the functions the AI has assumed, rather than only tracking the AI's performance of those functions. For the distributional shift mechanism, this means tracking performance disaggregated by subpopulation and context, rather than only tracking aggregate performance. For the proxy optimisation mechanism, this means measuring performance on dimensions that the system is not specifically optimised for, as a check on whether the proxy is still tracking the underlying objective.
The challenge of building these indicators into AI governance frameworks is not primarily technical. It is institutional: the incentives that govern AI deployment decisions systematically favour the metrics that show current success over the indicators that would reveal deferred failure. Building institutions that can resist these incentives requires the kind of structural independence and long-term mandate that are genuinely difficult to create and maintain in the political environments where AI governance decisions are actually made. The most dangerous AI failure does not announce itself as a failure. Governing it requires the foresight to invest in the detection of what does not yet look like a problem.
Topics in this article
You might also like
View all
The Hardest AI Safety Feature Is Saying No
Useful AI completes tasks. Safe AI also needs to know when to refuse.
Are We Giving AI Too Much Control?
Control does not transfer in one moment. It seeps out one small decision at a time.
Why a Black-Box Approach in AI Is Not Recommended
What we lose when the systems running our world stop being legible.